Open Datasets: GigaSpeech 2 – 30,000 Hours of Southeast Asian Multilingual Speech Recognition Open Source Dataset Released
The term “Giga” originates from “gigantic,” reflecting the vast audio resources available on the internet. However, the quality of these audio resources varies significantly, and high-quality audio-text pairs are particularly scarce and expensive to annotate, especially for low-resource languages. GigaSpeech, a highly successful open-source English dataset, addresses this issue by providing thousands of hours […]
Case Study|Building an Industrial-Scale Data Pipeline for Embodied AI
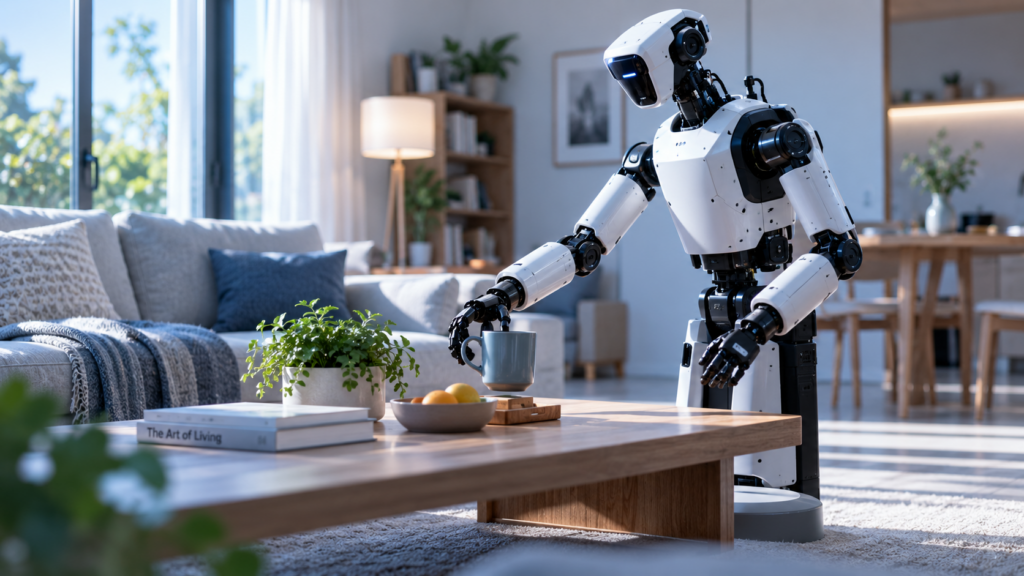
DataoceanAI helped an embodied AI company focused on world model training transform real-world data collection from project-based execution into a standardized, scalable, and continuously operating production system. Project Highlights 50,000+ hours/monthof high-quality usable data supported at scale Real-World EnvironmentsHome, office, retail, and industrial settings Multiple Collection ParadigmsUMI, first-person data collection, and robot teleoperation demonstrations The […]
Case Study|Scaling High-Quality 3DGS Data for Immersive VR Experiences
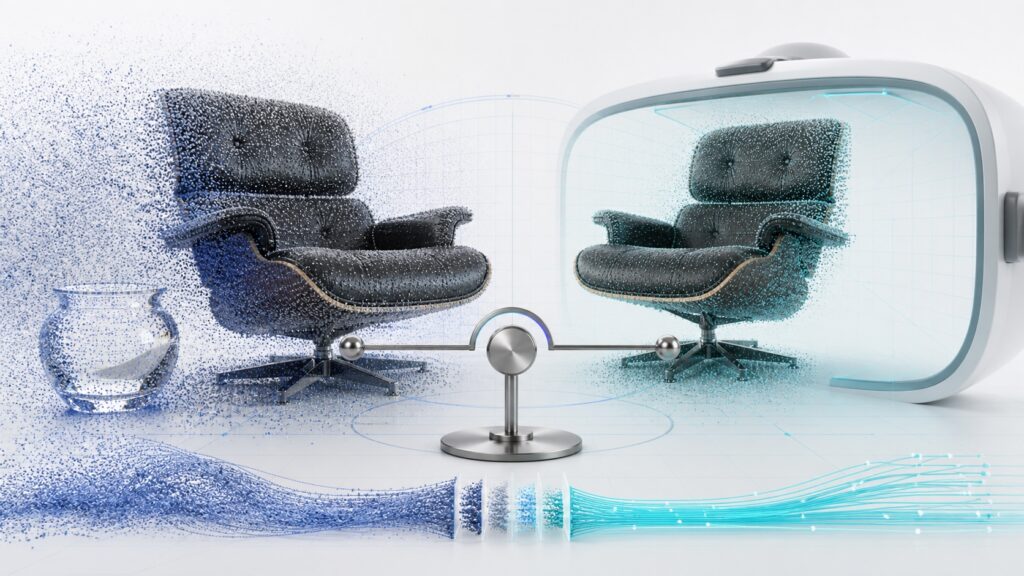
DataoceanAI helped a VR content and application developer build production-ready 3D Gaussian Splatting (3DGS) data across multiple object categories, balancing visual fidelity, data consistency, rendering performance, and compatibility with Unity and Unreal Engine. Project Highlights ·4K-Level Visual QualityPreserving key appearance, material, and surface details ·Unity + Unreal EngineValidated for integration and runtime performance across both […]
Case Study|Building Reliable Multimodal Data Pipelines for Intelligent Cockpits
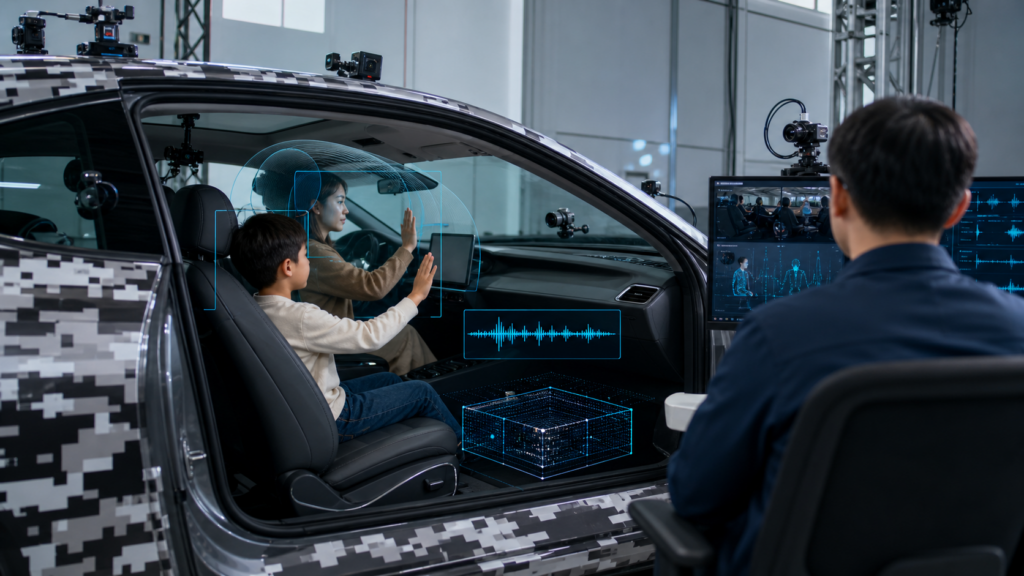
DataoceanAI helped a leading electric vehicle company build multimodal in-cabin datasets across diverse passenger profiles, sensor modes, interaction tasks, and vehicle scenarios—while keeping data quality, operational efficiency, confidentiality, and on-site safety under control. Project Highlights ·Multimodal CoverageRGB, infrared, video, audio, transcription, and participant metadata ·Diverse In-Cabin ScenariosAdults, seniors, children, twins, pets, gestures, and human-object interactions […]
Case Study|Building a Scalable Production Pipeline for Natural Duplex Conversation Data
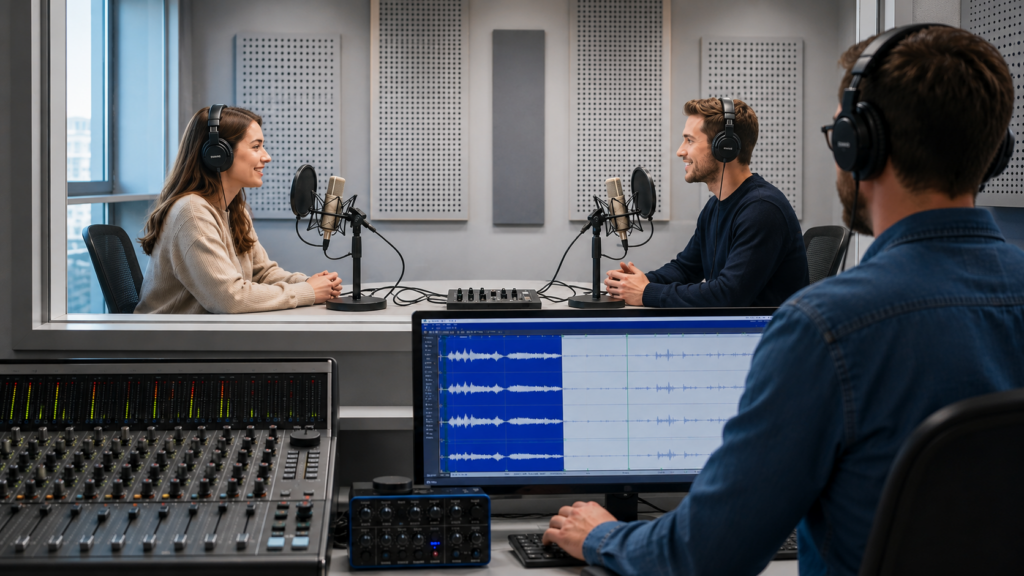
DataoceanAI helped a leading technology company deliver approximately 2,000 hours of natural duplex conversation data in five months, coordinating more than 1,000 participants across recruitment, recording, annotation, quality assurance, multi-channel synchronization, and compliance. Key Results The Challenge A leading technology company needed a large-scale natural conversational speech dataset to support the continued development and optimization […]
Case Study|Multilingual Emotional TTS Data Development Practice: Enabling More Natural Speech Synthesis
Project Overview Key takeaway: the real value of multilingual emotional TTS is not just language coverage. The goal is to keep linguistic accuracy, emotional expression, delivery efficiency, and compliance stable through standardized corpus design, collection management, quality control, and delivery workflows. Business need:A speech technology company needed emotional speech data spanning 14 languages or accents, […]
“Can You Interrupt AI Mid-Response?” Discover the Full-Duplex Power Behind GPT Realtime × Gemini — All Thanks to Full-Duplex Datasets!
Recently, OpenAI’s GPT Realtime and Google’s Gemini 2.5 made headlines, bringing voice assistants into a new era of “true real-time conversation.” You speak, and the AI replies instantly; even better, if the AI is mid-response, you can interrupt at any moment—and it handles it naturally, without awkward pauses. This is the closest AI has come […]